Ideogram 4.0
by Ideogram
Ideogram's open‑weight image model.
Frontier in‑image text, layout control, and 2K output.
Key features
Ideogram 4.0 has been retired on Morphic.
Use Ideogram 4.5, the newer model with better capabilities.
Technical specifications
Open
Open weights under a commercial license
0.97 OCR
X-Omni English OCR for in-image text
16 colors
Condition output on up to 16 hex colors
Up to 2K
256 to 2048 px per side, flexible ratios
Use cases
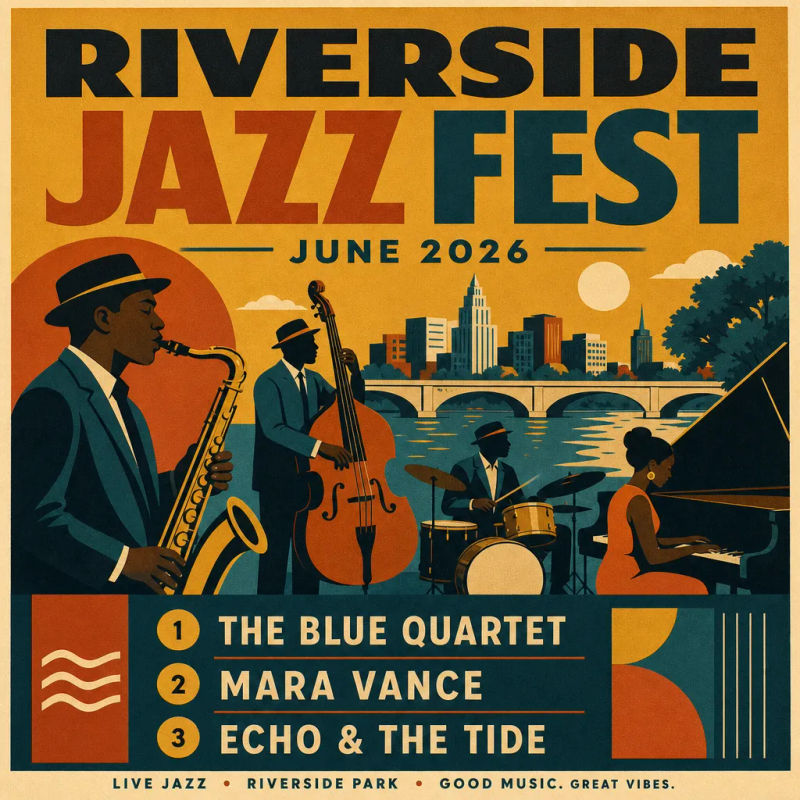
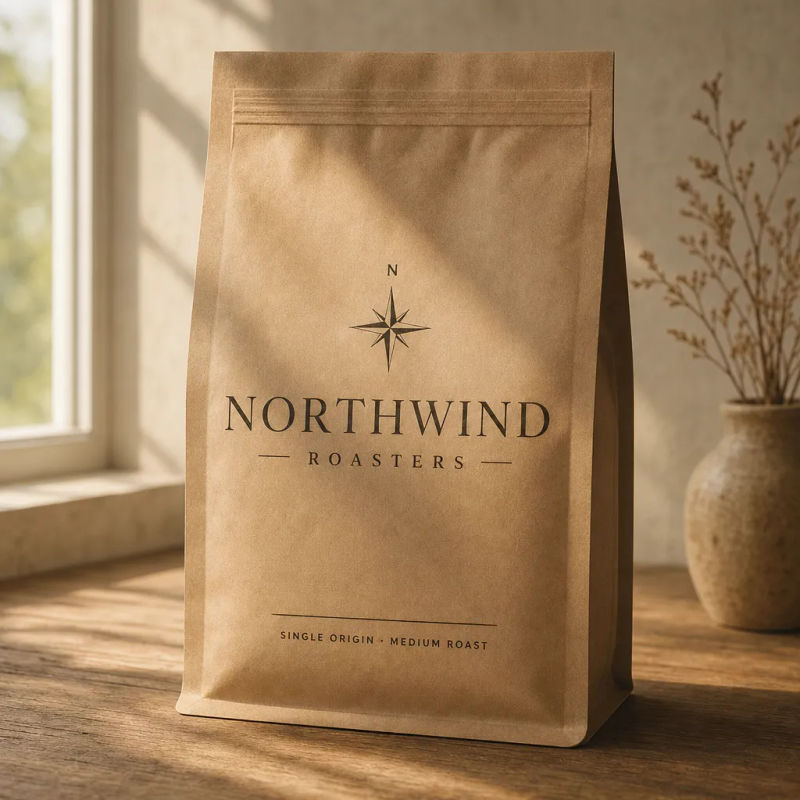
Posters and packaging
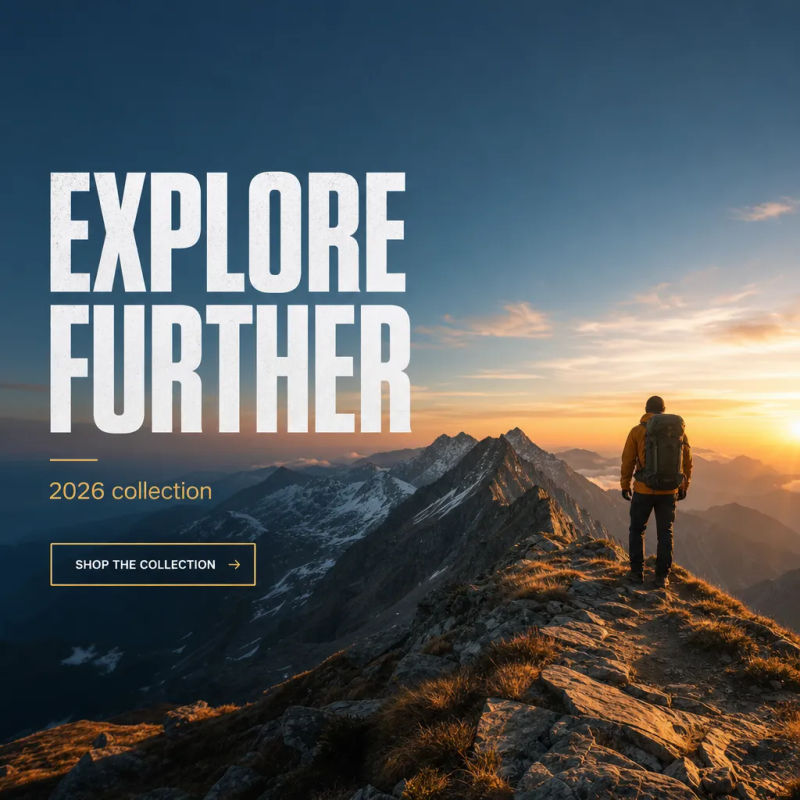
Design where the title, tagline, and small print all have to read correctly. Text renders legibly, not as shapes.
Multilingual campaigns
Localize one visual across markets by swapping the text per language while layout and palette stay fixed.
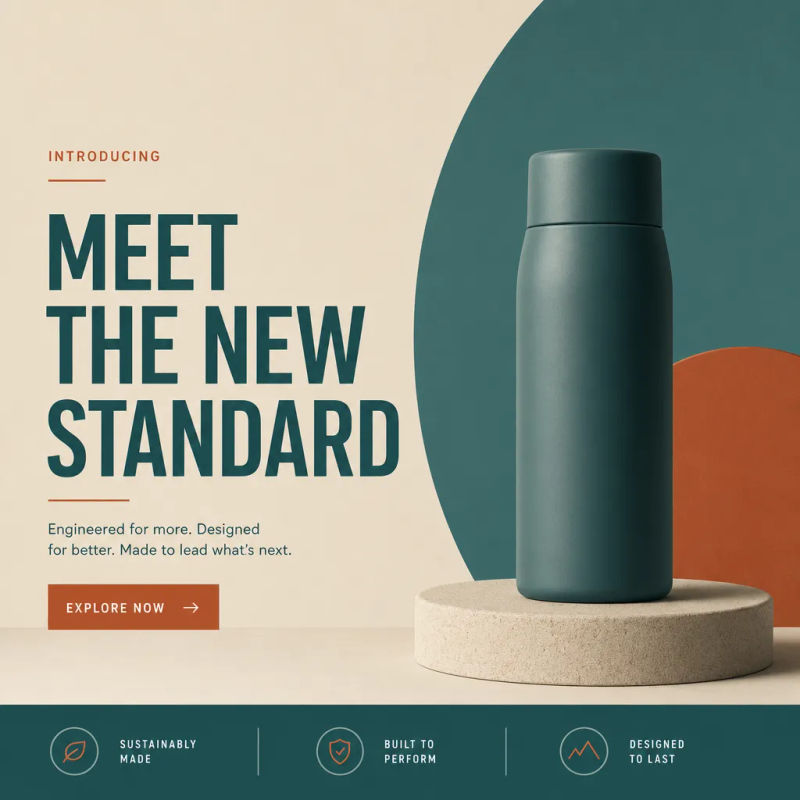
Brand-locked visuals
Feed the brand's hex palette into the prompt and every generation stays on-brand, tile to banner.
Unusual formats
One set of weights covers square thumbnails, widescreen, 2048 by 768 ultrawide banners, and social headers.
Programmatic generation
JSON prompts are built for code. Generate catalogs or ad variants from a script, each element typed and validated.
Self-hosted pipelines
Teams that can't use a third-party API can fine-tune the open weights and run them in their own infrastructure.
Prompt examples
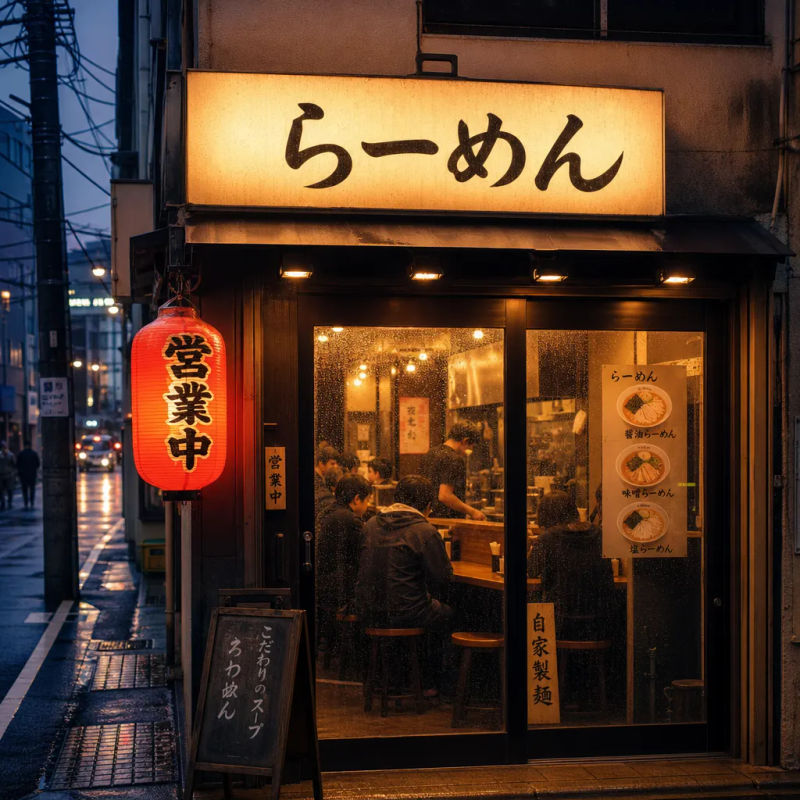
Multilingual sign
Tokyo storefront with accurate Japanese signage, soft rain, evening glow
Edit prompt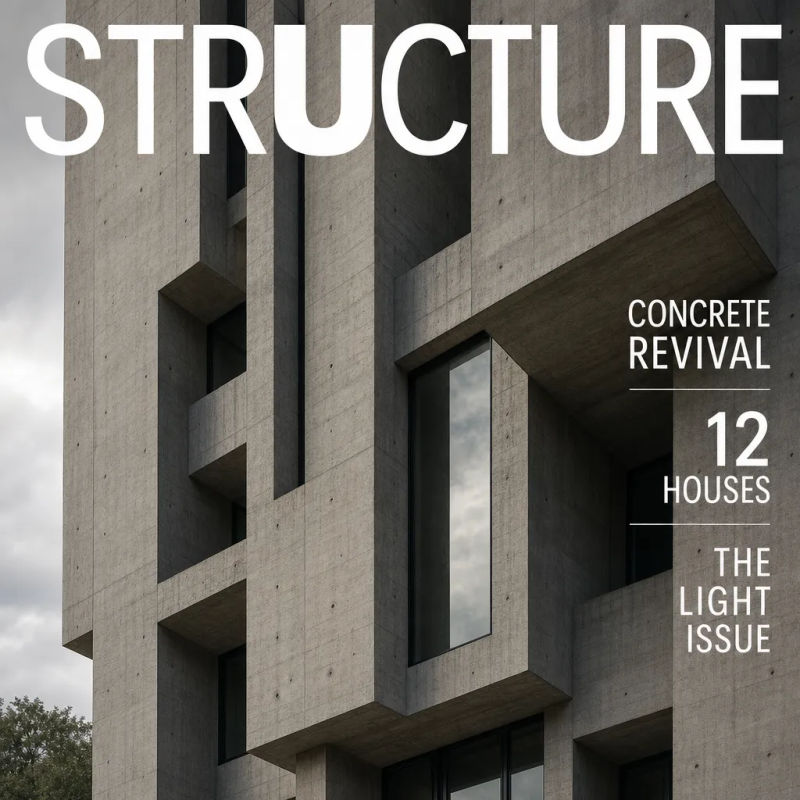
Overview
Ideogram 4.0 is a 9.3 billion parameter open-weight text-to-image model from Ideogram, released on June 3, 2026. It leads the open-weight field at its size on in-image text rendering, scoring 0.97 on the X-Omni English OCR benchmark, and pairs that with bounding-box layout control, structured JSON prompting, color palette conditioning, and output up to 2K. The weights, inference code, and prompting guide are public, with quantized builds that run on a single 24 GB GPU.
What Ideogram 4.0 does differently
Most image models take a sentence and return pixels, so text comes out misspelled and placement is a roll of the dice. Ideogram 4.0 was trained exclusively on structured JSON captions, so a prompt can spell out each element: where it sits in the frame, how it is styled, the exact string a text element should render, and the hex colors the image must stay inside. That structure makes results precise and repeatable, which matters for design work that ships as posters, packaging, banners, and UI rather than one-off art.
Ideogram 4.0 and Morphic
On Morphic, Ideogram 4.0 has been replaced by its successor, Ideogram 4.5, which keeps the same strength in in-image text and adds precise, repeatable editing. Select Ideogram 4.5 in Copilot or on the Canvas and it runs alongside the rest of the image line, plus video, speech, and music, in one workspace. To compare AI image models on text accuracy and maximum resolution, see how the Ideogram line stacks up against Nano Banana 2, GPT Image 2.5, and Recraft V4.1 Pro.
Ideogram 4.5 on Morphic generates at nine aspect ratios, 9:16, 2:3, 3:4, 4:5, 1:1, 5:4, 4:3, 3:2, and 16:9, at 1080p or 1440p. Reach for it when the words inside the image have to be spelled correctly and set well. There is a dedicated Ideogram 4.5 image editor if you want to start from an image you already have.
Simple pricing
Get started for free today, with the option to upgrade or cancel anytime.
Basic
2400 monthly credits
1 user only
All models
Workflows
Standard
3625 monthly credits
1 user only
All models
Workflows
Pro
6350 shared monthly credits
1 user
All models
Workflows
Max
24650 shared monthly credits
1 user
All models
Workflows
Enterprise
For higher limits
Custom
pricing and billing terms

Free
For playing around
$0
forever free
FAQs
Vidu Q4
Shengshu Technology
Shengshu's latest video model. Up to 12 reference images and 3 voices held consistent across one clip, with native audio from 540p to 4K.
Nano Banana 2.1
Google DeepMind
Google DeepMind's new Flash image model. Better design, cleaner edits, steadier characters.
Flux 3 Image
Black Forest Labs
Black Forest Labs' control-first image model. Place every element, edit one box at a time.
Ideogram 4.5
Ideogram
Ideogram's precision edit model. Stack edit on edit, with no drift or artifacts.